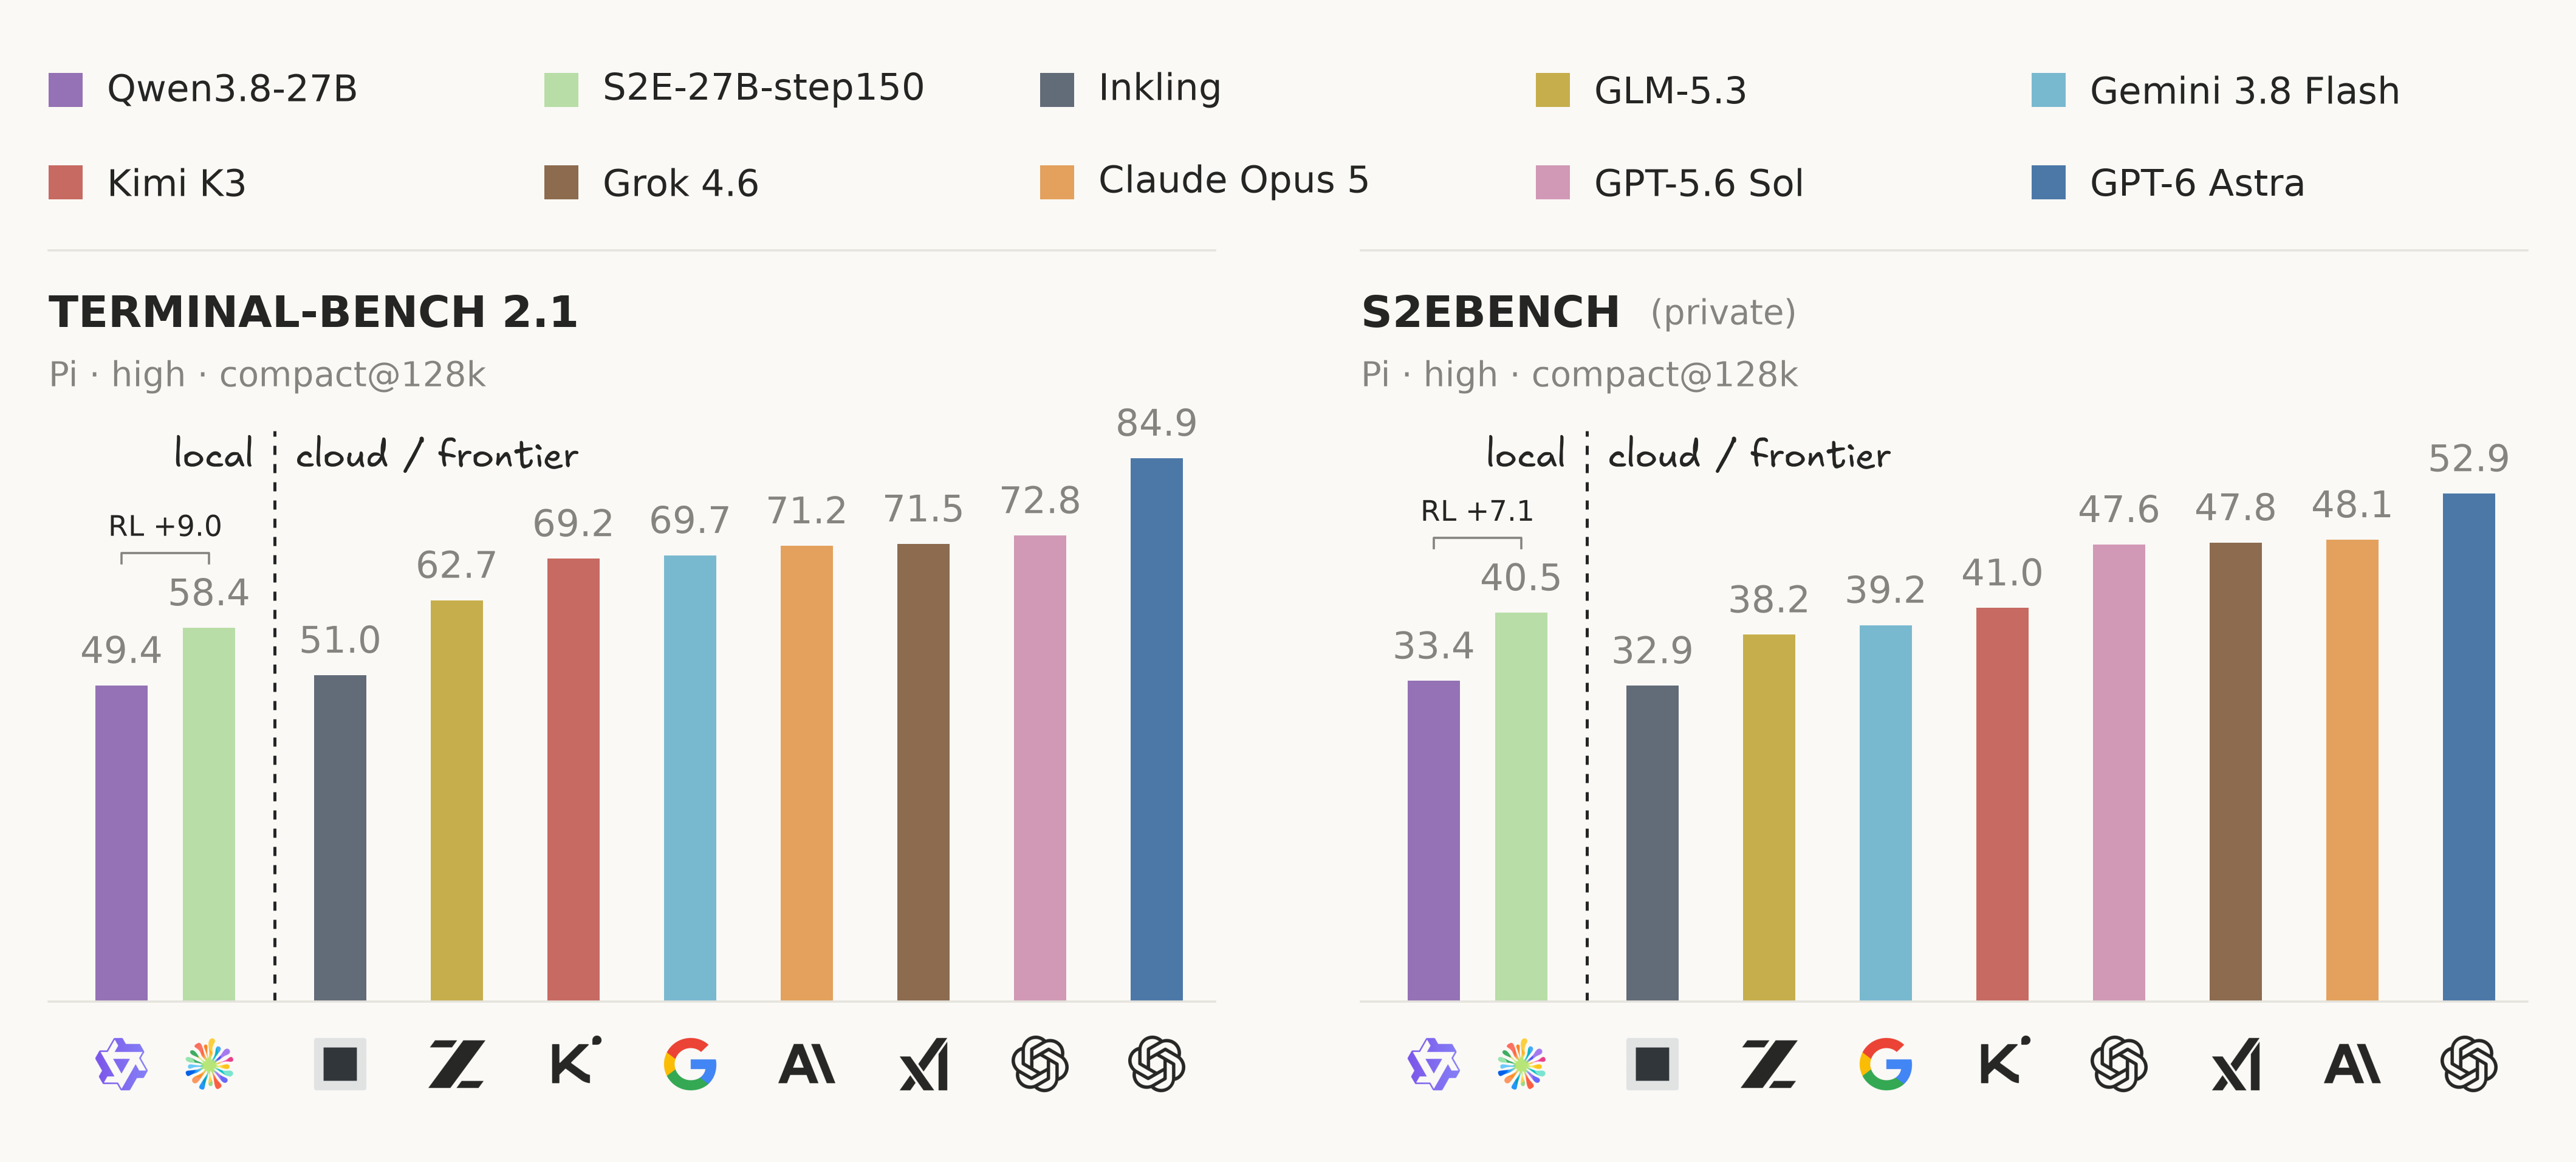
 RL Data Scaling
Binfeng Xu
Agent Research · NVIDIA
I’m a researcher at Nvidia advancing RL systems for terminal agents, coupling training infra, recipe, data/env and harness design.
Earlier, I built Polar (ProRL-Agent-Server), the first framework realizing scalable any-harness RL in the open. To democratize agentic RL dataset, Skill2Env turns public Agent Skills into verifiable terminal tasks. To stablize long-horizen async RL for agents, I co-developed RL recipes like seq-level KL gating (FlashREINFORCE) and zero train-inference mismatch (REINFORCE Zero).

Research
RL Data Scaling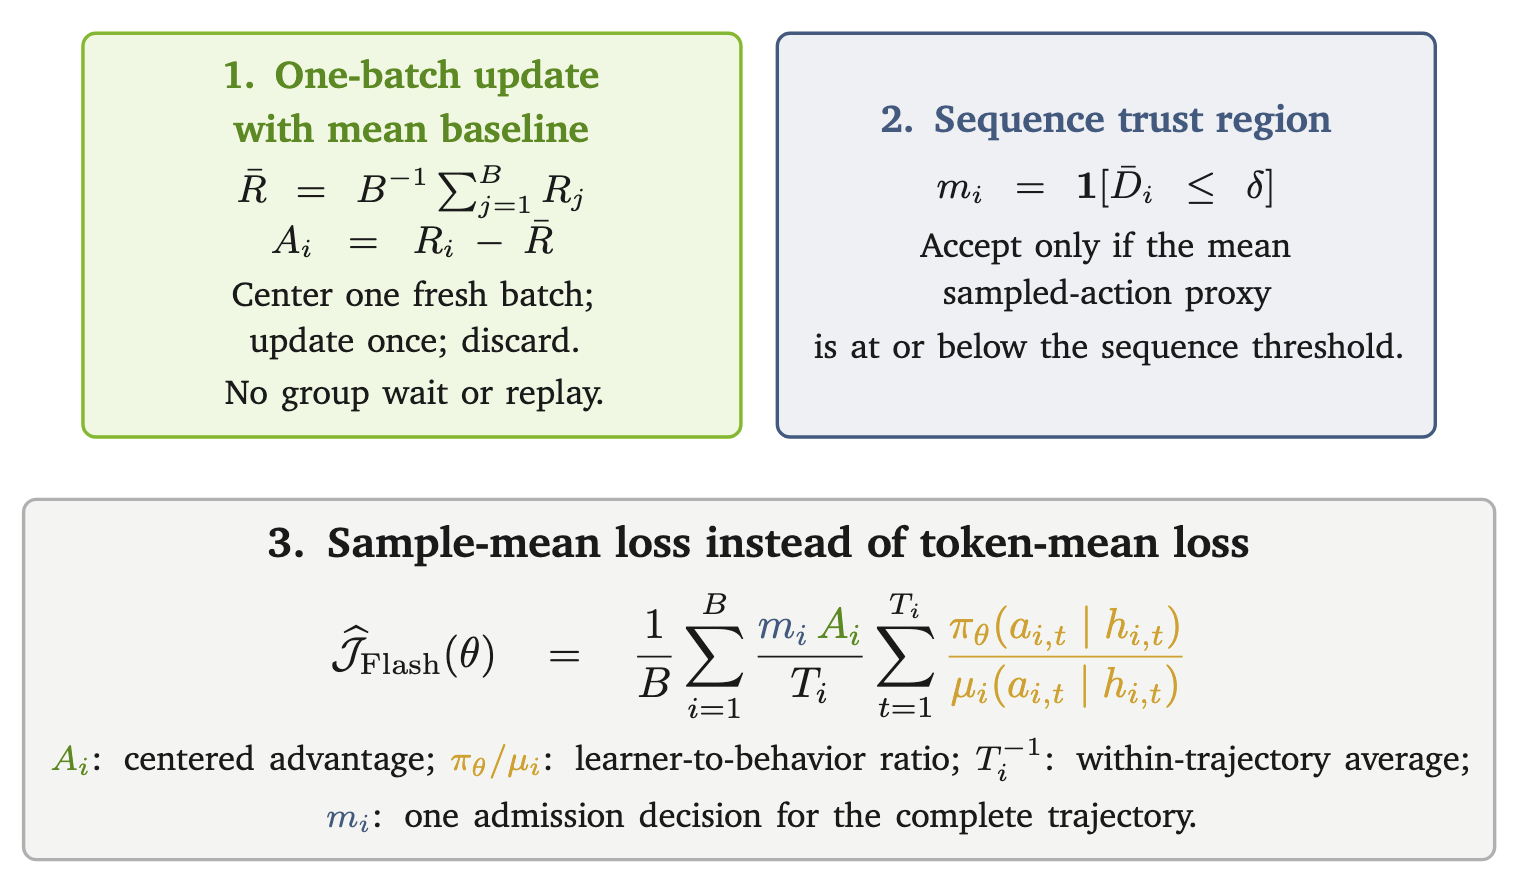 Async RL Recipe
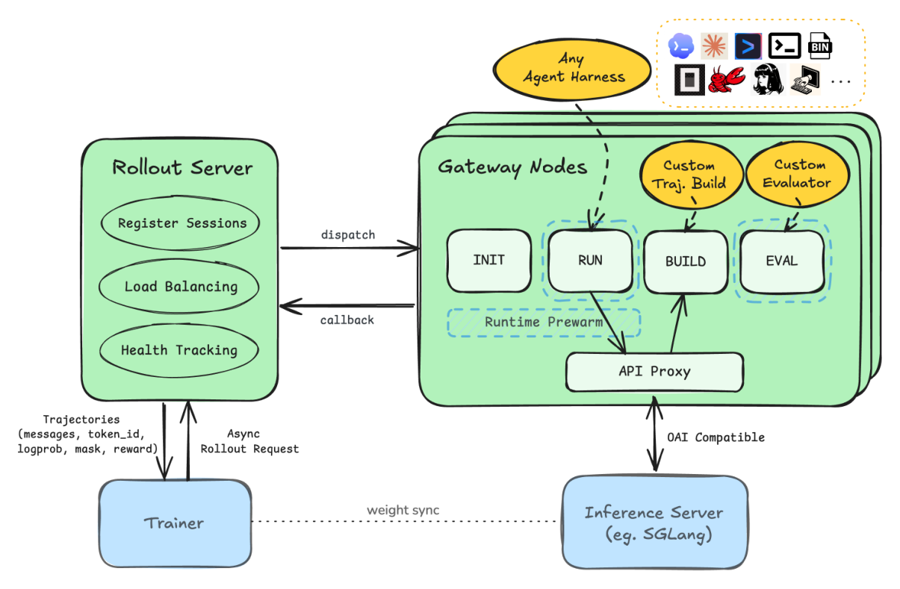 Agent RL Infra
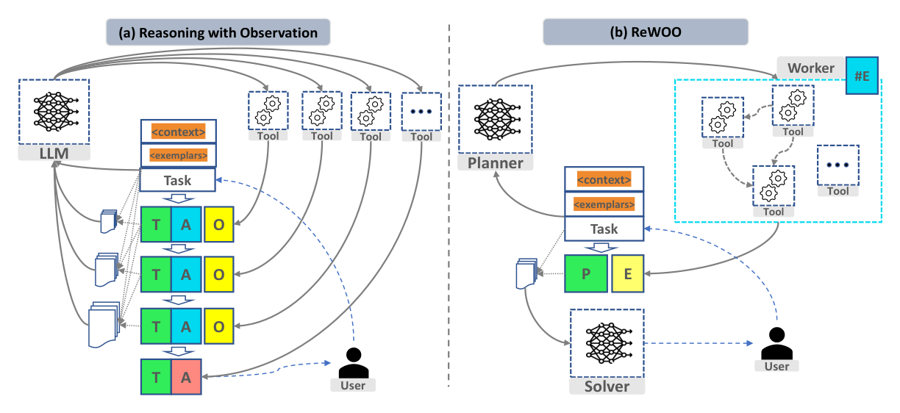 Agent Harness
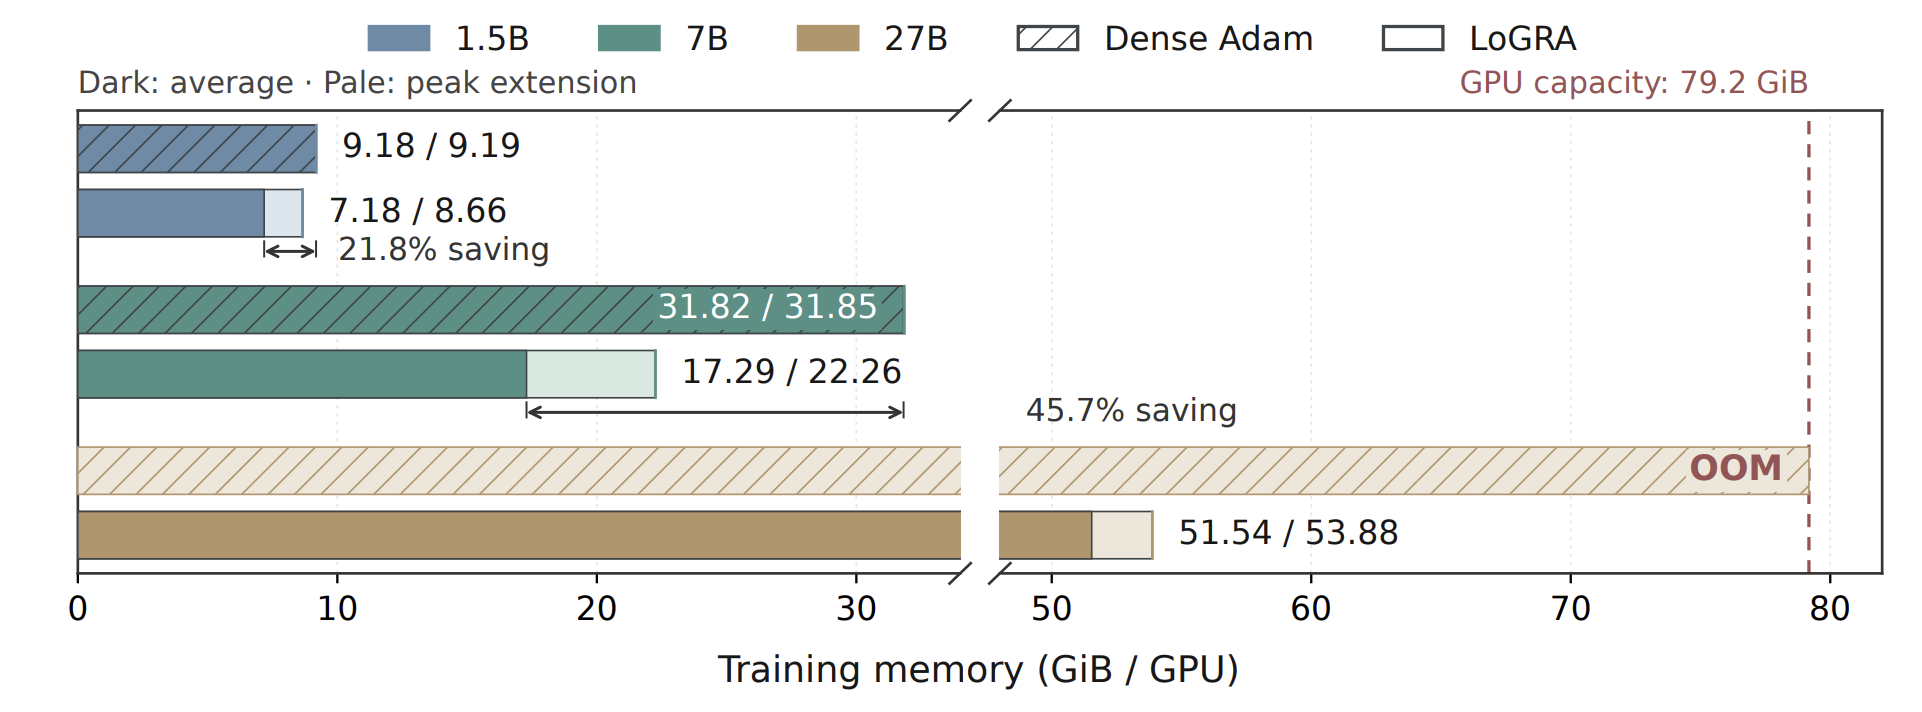 Memory Efficient RL
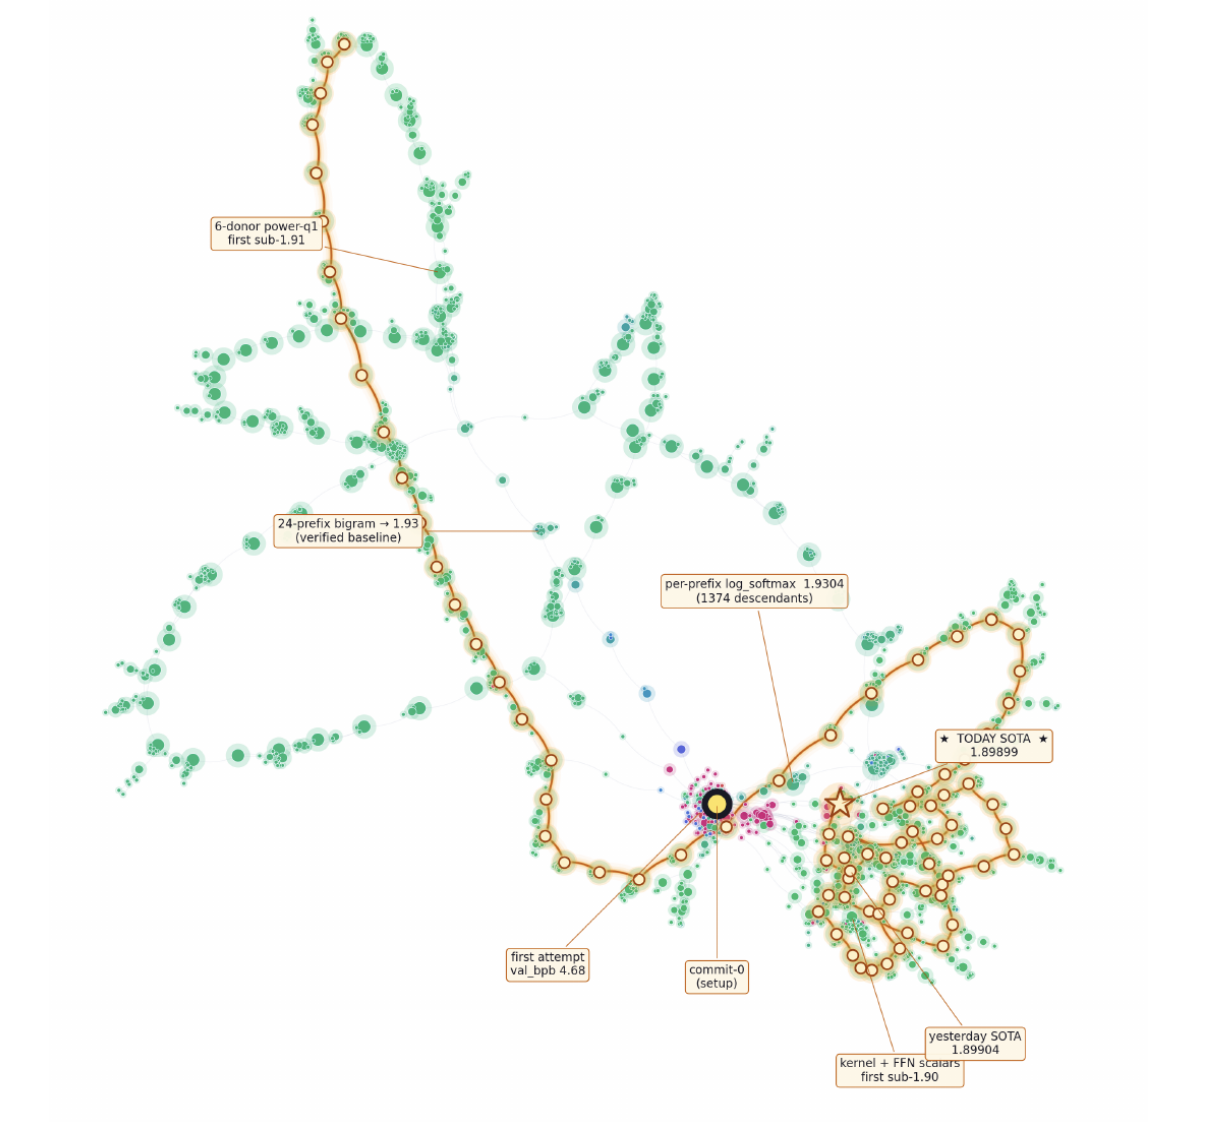 Agent Harness / AutoResearch
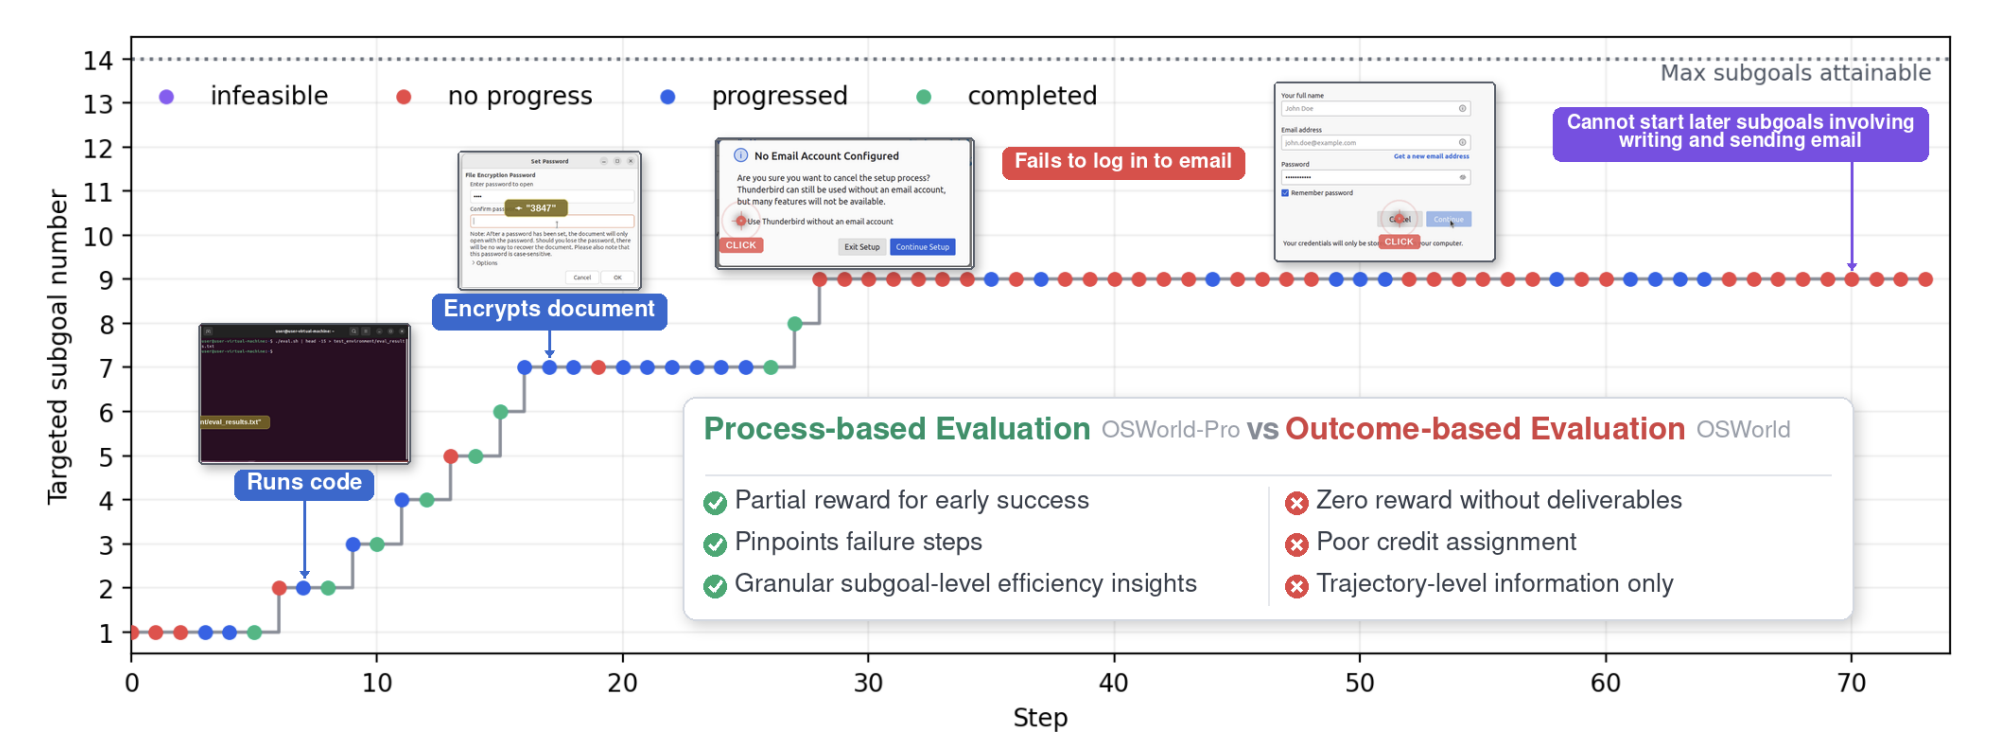 Computer-use Agent
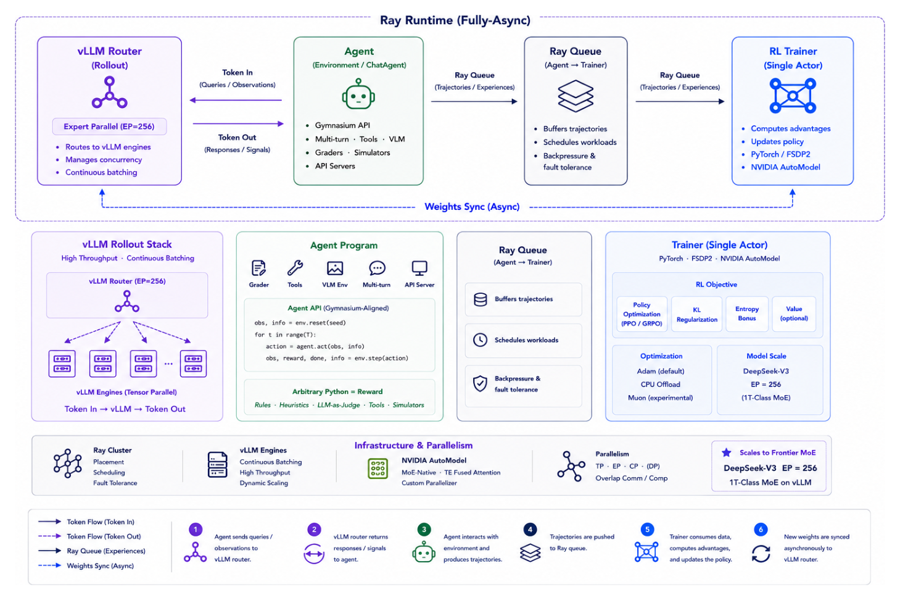 Agent RL Infra
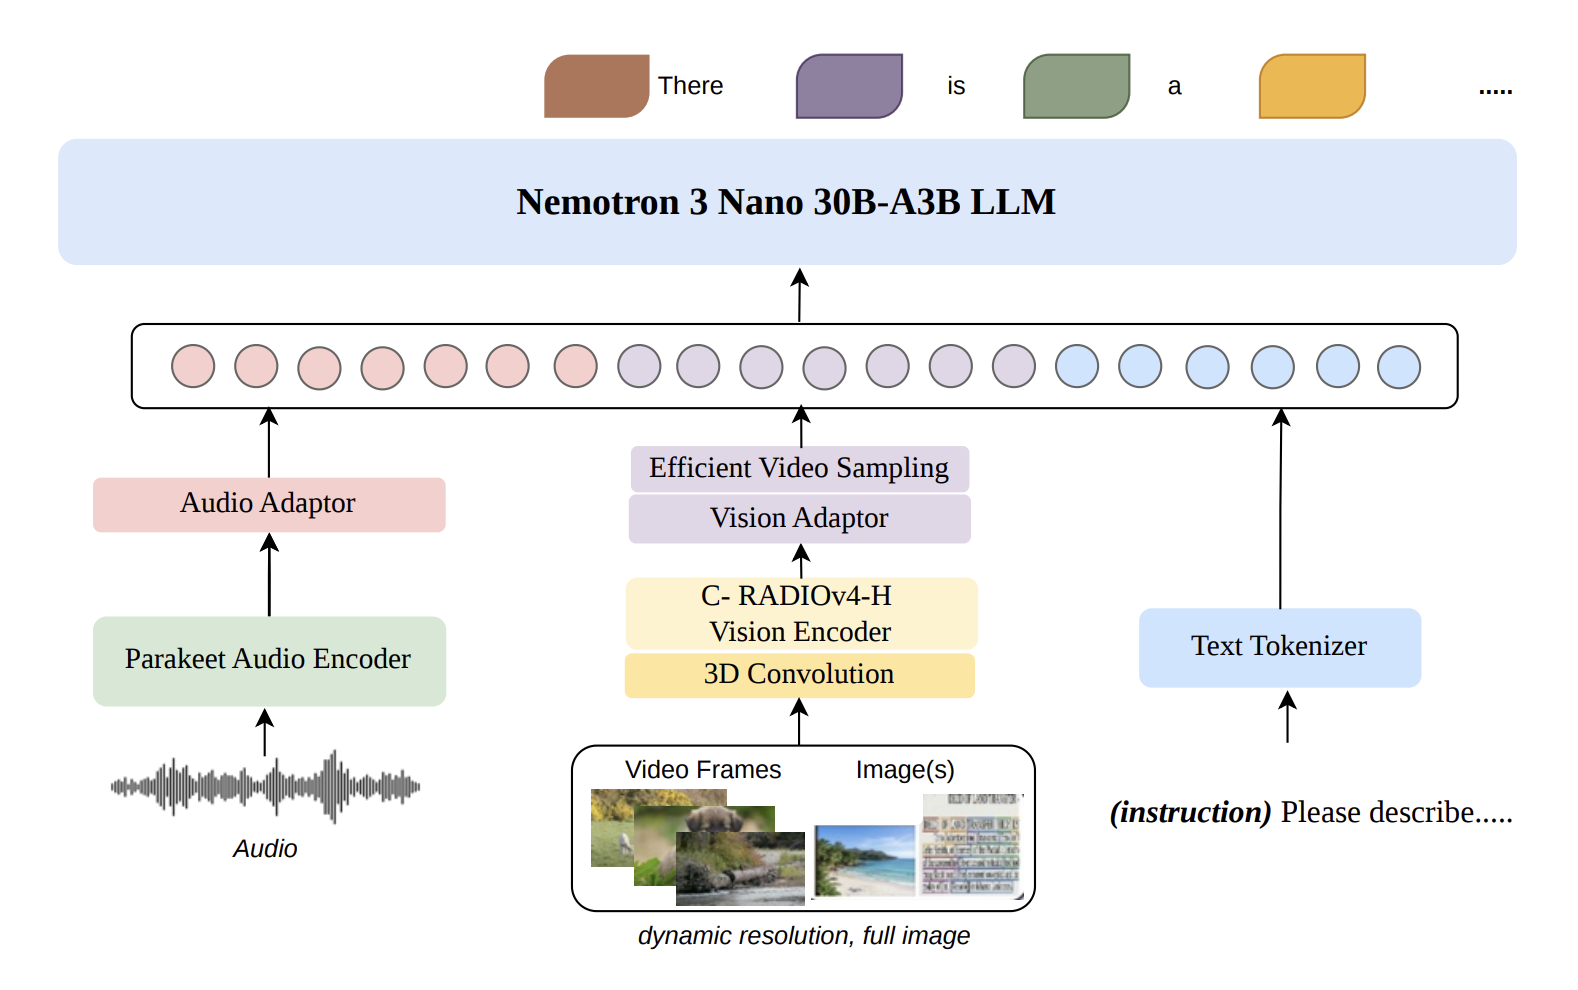 Multimodal LLM
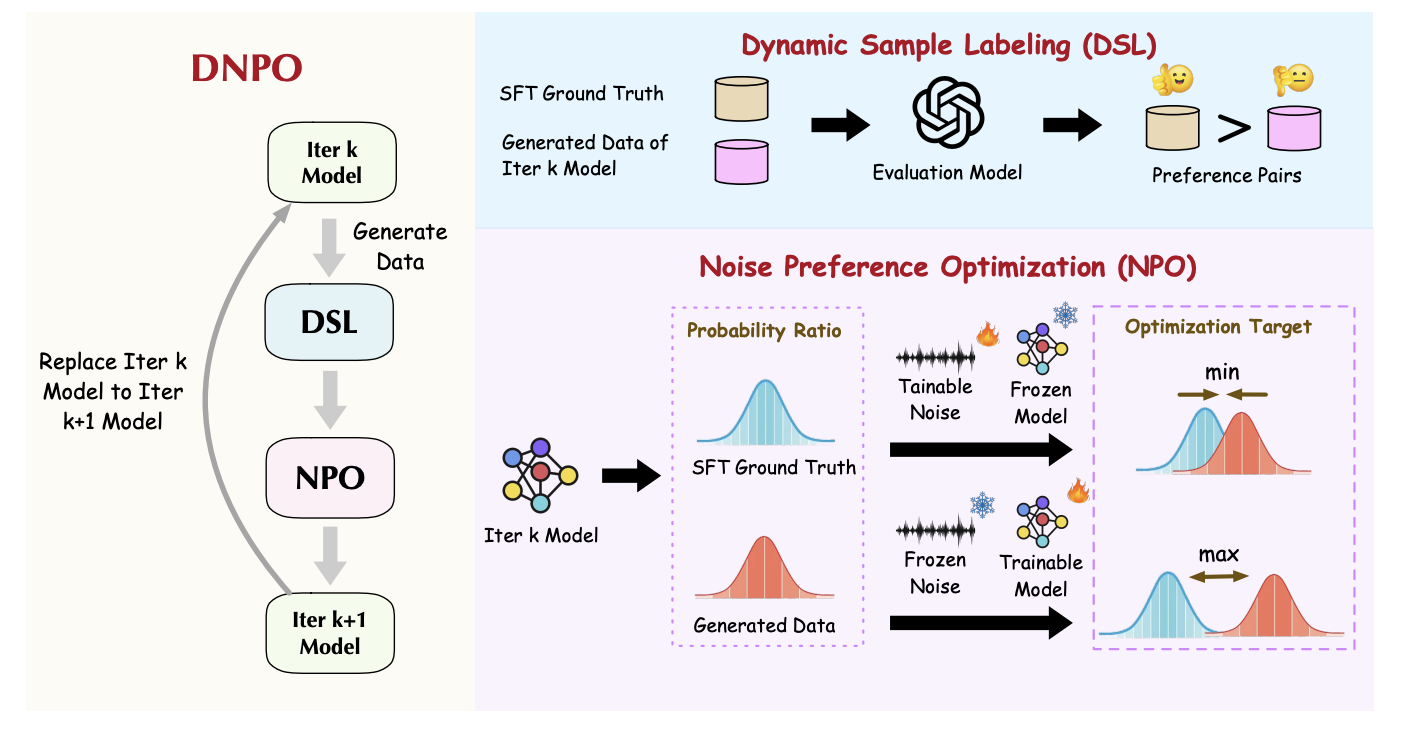 RL Recipe
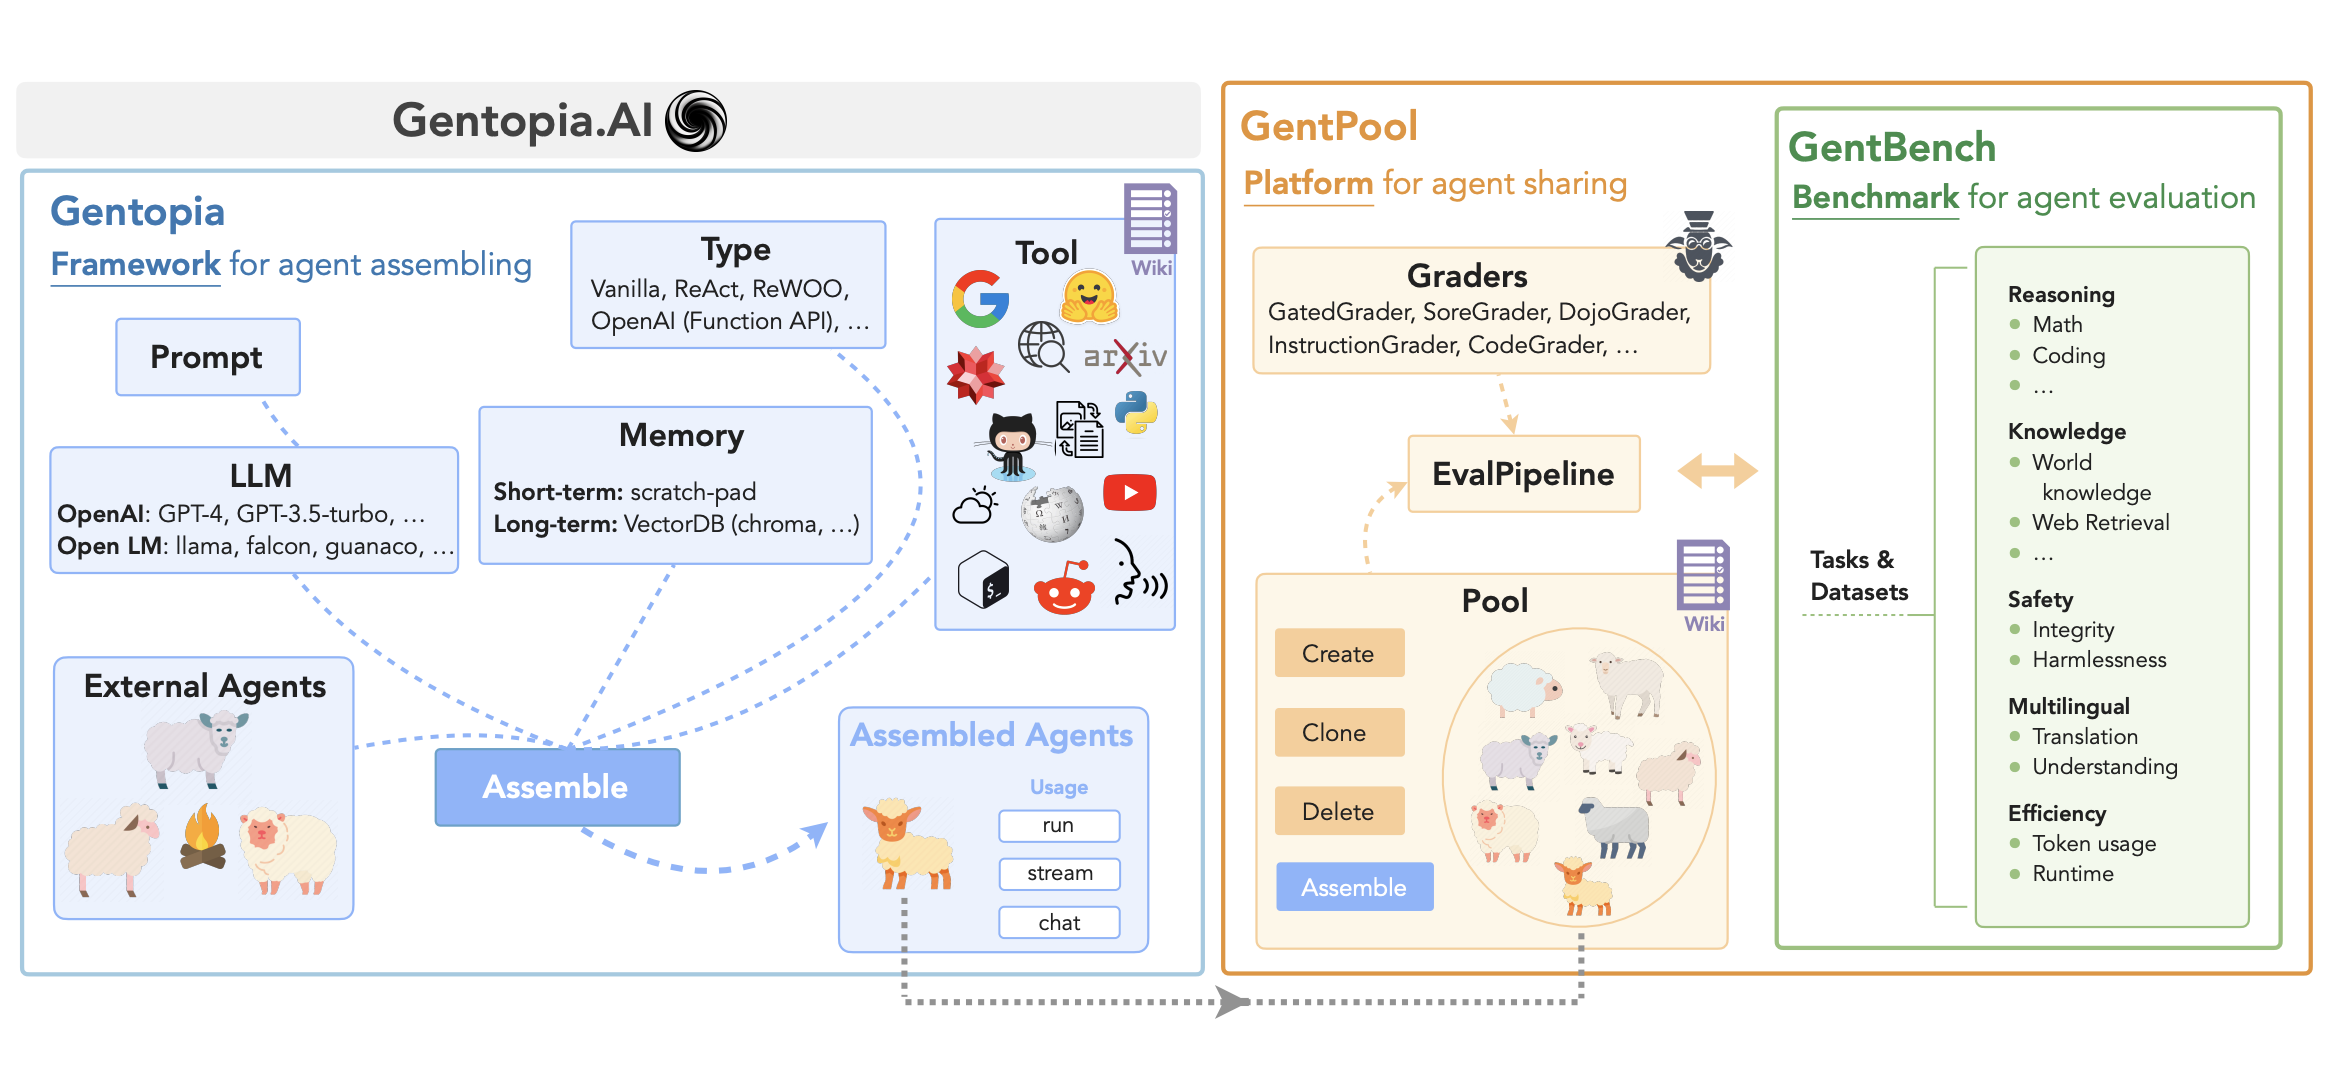 Agent Harness
Blog
Misc
I play all games by Hidetaka Miyazaki. I played Kaggle to learn ML during school, where I ranked 1% (657th of 200,000+). I enjoy art, training large neural nets and petting cats.
